Projects
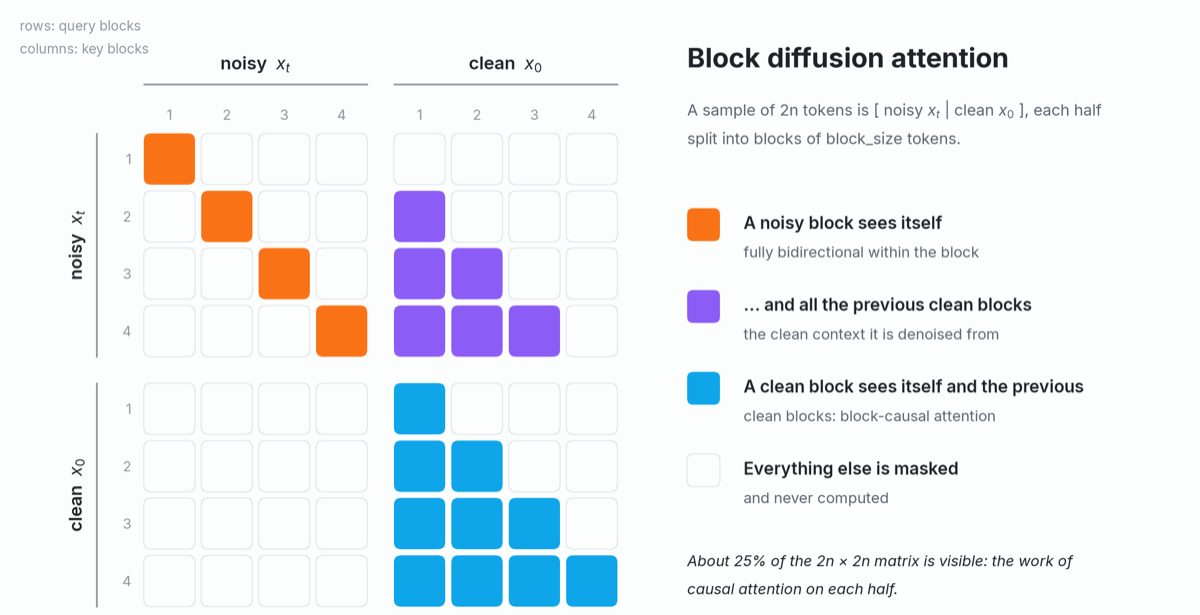
Fast Diffusion Attention
Yuezhou Hu, Kurt Keutzer, Chenfeng Xu
Block diffusion training at FlashAttention speed: attention kernels with the block diffusion mask built into FlashAttention-3 on Hopper and FlashAttention-2 on Ampere and Ada. A training step runs at 0.96-1.10x the throughput of FlashAttention-3 doing the same work.
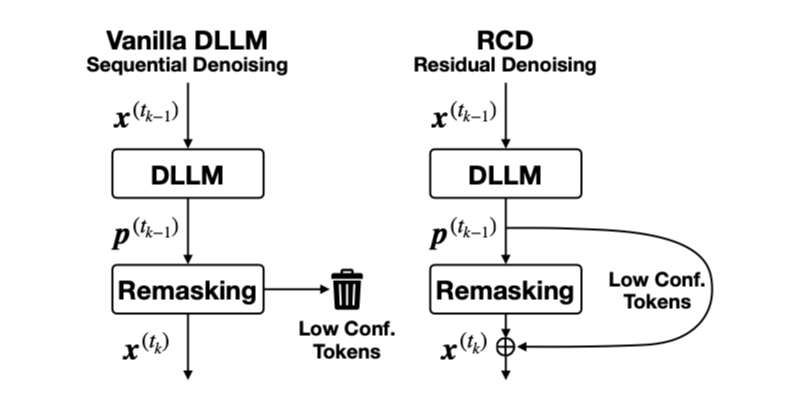
Residual Context Diffusion
Yuezhou Hu*, Harman Singh*, Monishwaran Maheswaran*, et al. · ICML 2026
Diffusion LLMs discard the predictions of the tokens they remask at every denoising step. RCD turns them into contextual residuals for the next step: it improves accuracy by 4–11 percentage points, nearly doubles accuracy on AIME, and reaches the baseline’s peak accuracy with up to 4–5x fewer denoising steps.