Residual Context Diffusion
Unleashing the Potential of Diffusion LLMs via Residual Denoising
1University of California, Berkeley 2Apple
*Equal contribution †Equal advising / Corresponding author
ICML 2026
Demo Video
About RCD
Diffusion Large Language Models (dLLMs) offer parallel decoding benefits but often trail autoregressive models in accuracy. This is due to the "remasking" strategy which wastes intermediate computation on tokens that remain undecoded. We propose Residual Context Diffusion (RCD), a novel paradigm that transforms this wasted computation into a guiding signal. By treating latent representations of low-confidence tokens as residual updates, RCD allows models to progressively refine their knowledge. We validate RCD on long chain-of-thought reasoning (SDAR) and short chain-of-thought instruction following (LLaDA), and a standard dLLM converts to RCD with only ~300 million training tokens. Our method achieves 4–11 percentage point gains on GSM8K/MATH500 and doubles accuracy on competition-level AIME benchmarks while requiring up to 4–5× fewer steps at the baseline's peak accuracy.
News
- [2026/06] RCD inference is now reference-free: a cold-start initialization of the residual context removes the need for a reference model during generation.
- [2026/06] JetEngine released: a CUDA/Triton inference engine for block diffusion LLMs, optimized for RCD's residual denoising with continuous batching and fused kernels.
- [2026/05] RCD is accepted at ICML 2026.
- [2026/02] Project page, arXiv paper and models are released.
Why Residual Context Diffusion?
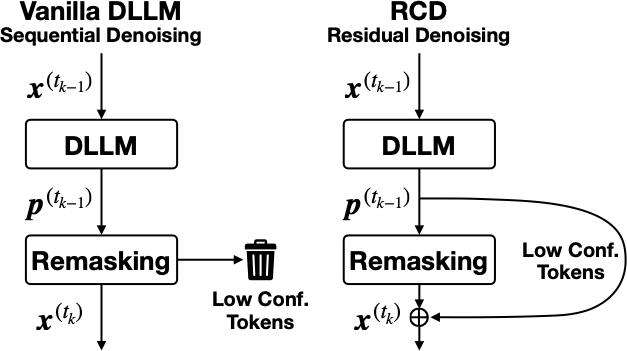
Diffusion LLMs (dLLMs) achieve high efficiency through parallel decoding, yet they consistently struggle to match the accuracy of Autoregressive (AR) models. While this gap is partly rooted in the inherent challenges of training dLLMs, it is further exacerbated by the inference-time "Remasking" strategy:
The Problem: Information Loss
In each denoising step, standard dLLMs discard all tokens that fall below a confidence threshold, resetting them back to [MASK]. This wastes the intermediate computation spent on low-confidence tokens, forcing the model to "start from scratch" at those positions in the next step.
The RCD Solution: Residual Recycling
Instead of discarding uncertain tokens, RCD treats them as Residual Context. By aggregating these "soft tokens" based on their Entropy, we transmit a continuous, semantically-rich signal to the next iteration, enabling the model to refine its "thinking" rather than re-guessing.
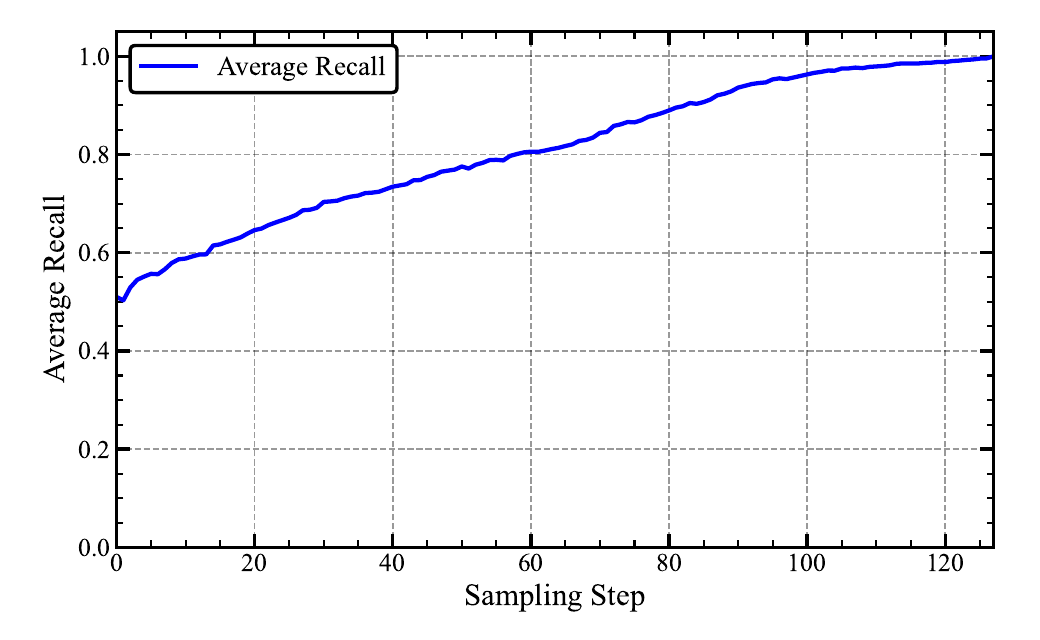
The discarded distributions are informative. Figure 2 follows LLaDA on GSM8K: at every sampling step, it measures the fraction of the final decoded tokens that already appear among the top-5 predictions at their positions. About half of them do at the very first step, and the fraction rises steadily from there: the intermediate distributions point toward the final answer, and remasking throws this information away.
The RCD Method
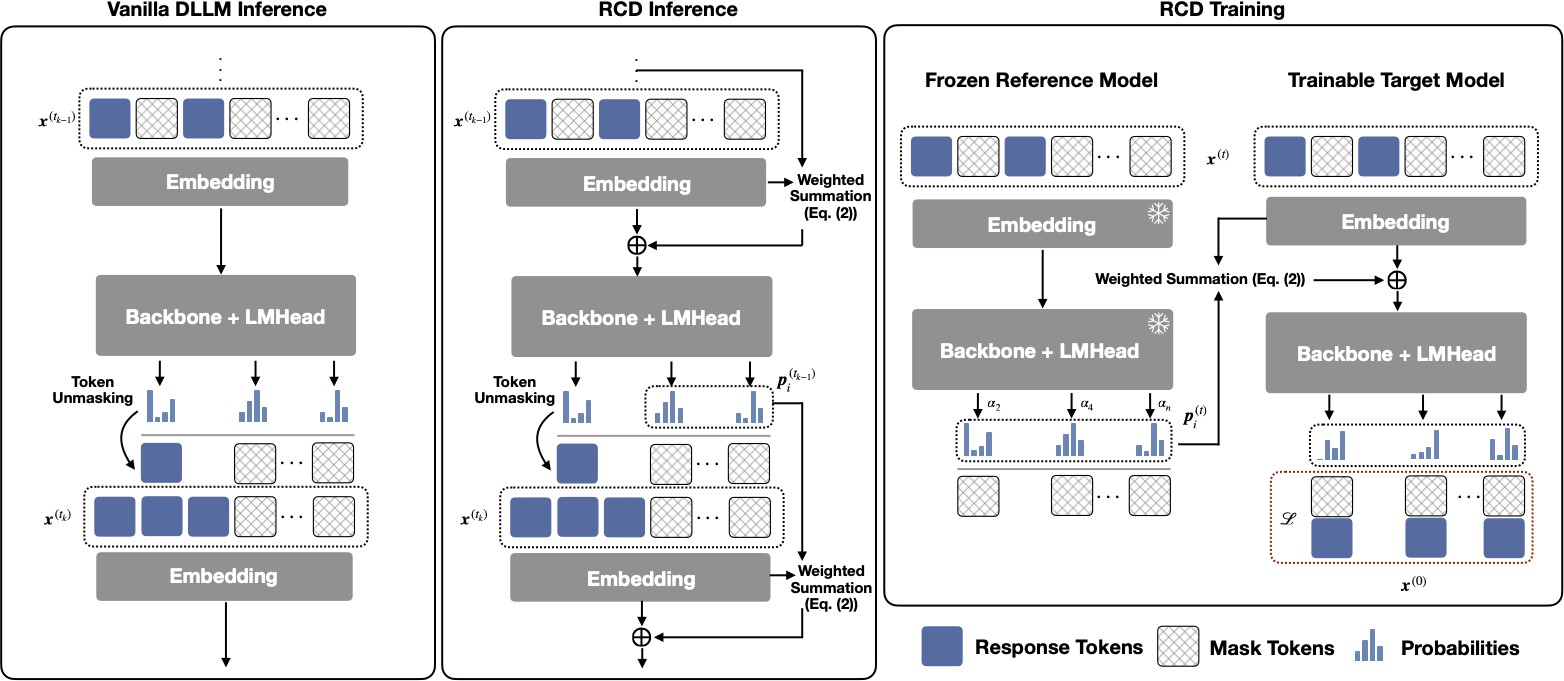
- Vanilla dLLM (left): Tokens not selected are reverted to static mask embeddings, discarding rich probability information.
- RCD Inference (center): Calculates a weighted sum of unselected distributions (residuals) to refine ambiguous tokens over time.
- RCD Training (right): A Decoupled Strategy: A frozen Reference Model provides stable targets to train the Target Model's residual awareness.
RCD introduces an Entropy-Based Embedding Aggregation mechanism. Instead of discarding uncertain tokens, we calculate their normalized Shannon entropy to determine their contribution to the next step's input.
- Residual Injection: Integrates soft-token information into masked positions.
- Two-Stage Training: Uses a lightweight Reference Model to provide stable proxy signals, overcoming the instability of recursive loops.
- Self-Correction: Temperature-scaled entropy alignment during inference to match training statistics.
Entropy-weighted residual
At every denoising step, each position that stays masked still has a predicted distribution \(\boldsymbol{p}_i\) over the vocabulary. RCD turns it into a residual vector, a "soft token", using the model's own input embedding codebook \(\boldsymbol{E}\):
\[ \boldsymbol{\Delta}_i = \sum_{j=1}^{V} p_{i,j}\, \boldsymbol{E}_j \]
At the next step, the input of a masked position interpolates between the mask embedding and this residual: a highway-style connection, which keeps the input on the scale of ordinary token embeddings. Decoded positions keep their usual embedding.
\[ \tilde{\boldsymbol{e}}_i = (1 - \alpha_i)\, E([\mathrm{M}]) + \alpha_i\, \boldsymbol{\Delta}_i \]
The weight is the normalized Shannon entropy of the prediction, where \(V\) is the vocabulary size. Uncertain, high-entropy positions may carry the most critical information for the next steps, so they receive the most residual context.
\[ \alpha_i = \frac{H(\boldsymbol{p}_i)}{\log V} = -\frac{1}{\log V} \sum_{j=1}^{V} p_{i,j} \log p_{i,j} \in [0, 1] \]
Two-stage training
Training the model on its own residuals would mean unrolling the denoising loop and backpropagating through time, which is prohibitively expensive in memory. RCD decouples producing the residuals from using them:
- Reference model. A lightweight dLLM is fine-tuned with the standard masked objective, then frozen. For SDAR, a 1.7B model guides the 4B and 8B target models.
- Residual-aware target model. For each masked training sequence, the frozen reference model provides the distributions and the entropy weights. The residuals are built with the target model's embedding codebook, so that they lie in its latent space, and the target model is trained with the standard cross-entropy loss, in a single step.
The recursive loop becomes ordinary supervised training. A standard dLLM converts to RCD with about 300M tokens, and for an 8B target with a 1.7B reference model, the extra training cost stays within 50%.
Inference
At inference, the target model feeds itself: the logits of each step give the residuals and entropy weights of the next one. A residual temperature \(T_{\mathrm{res}}\) softens the distributions they are computed from, which calibrates the entropy weights to the statistics the model saw in training. At the first step there is no previous residual: it is either set to zero (cold start) or produced by one call of the reference model (warm start). With the cold start, used for SDAR, generation needs no reference model at all.
Experimental Results
We evaluate RCD on two kinds of dLLMs: the SDAR family (4B and 8B; semi-autoregressive, with blocks of 32 or 64 tokens and KV-cache reuse) on long chain-of-thought math reasoning, and LLaDA (8B; bidirectional) on short chain-of-thought instruction following. SDAR's chat models are fine-tuned into reasoning models on the long samples of OpenR1-Math-220k (~300M tokens), and LLaDA's base model on a 1M-sample subset of OpenMathInstruct-2 (~400M tokens). The baseline, Sequential Denoising (SeqD), is the same model fine-tuned on the same number of tokens, without residual context.
Main Results
RCD consistently beats Sequential Denoising (SeqD) across every model / block-size setting, with the largest gains on competition-level AIME24/25, where accuracy often more than doubles. Confidence threshold 0.85; SeqD/RCD use a 16,384 sequence length, Chat uses 512 tokens (1,024 for AIME). Greedy decoding on GSM8K and MATH500; AIME24/25 report Pass@1 over 16 samples at temperature 0.6.
| Model | Variant | GSM8K† | MATH500 | AIME24 | AIME25 |
|---|---|---|---|---|---|
| SDAR-4B-b32 | Chat‡ | 86.13 | 50.20 | 5.83 | 2.50 |
| SeqD | 81.73 | 61.20 | 6.04 | 11.88 | |
| RCD | 84.91 | 65.40 | 9.17 | 17.08 | |
| SDAR-4B-b64 | Chat‡ | 85.90 | 49.80 | 6.25 | 1.67 |
| SeqD | 78.85 | 56.80 | 4.17 | 7.29 | |
| RCD | 87.04 | 68.40 | 11.04 | 14.79 | |
| SDAR-8B-b32 | Chat‡ | 88.40 | 50.00 | 6.46 | 4.17 |
| SeqD | 86.50 | 65.80 | 11.67 | 14.79 | |
| RCD | 90.45 | 76.20 | 18.96 | 20.00 | |
| SDAR-8B-b64 | Chat‡ | 88.32 | 51.60 | 5.20 | 2.50 |
| SeqD | 82.87 | 64.20 | 7.08 | 9.79 | |
| RCD | 86.05 | 74.40 | 18.75 | 16.04 |
† Potential data contamination was observed in the original Chat models on GSM8K, which may inflate the Chat baseline. ‡ Chat variants are instruction-following models; SeqD/RCD are further adapted for mathematical reasoning.
| Model | Variant | GSM8K | MinervaMath |
|---|---|---|---|
| LLaDA | Base* | 70.30 | 31.40 |
| SeqD | 75.74 | 31.10 | |
| RCD | 78.09 | 37.00 |
LLaDA (global-attention dLLM): sequence length 512, single-token-per-step decoding. * LLaDA-Base results are from the original LLaDA paper.
- Doubles hard-task accuracy: on SDAR-8B-b64 AIME24, RCD lifts accuracy from 7.08 → 18.75.
- Scales with size & block: gains of 4–11 percentage points when scaling from 4B to 8B, widening as block size grows.
- Generalizes across architectures: on global-attention LLaDA, RCD adds a ~6 point absolute gain on MinervaMath.
Efficiency: Accuracy vs. Parallelism
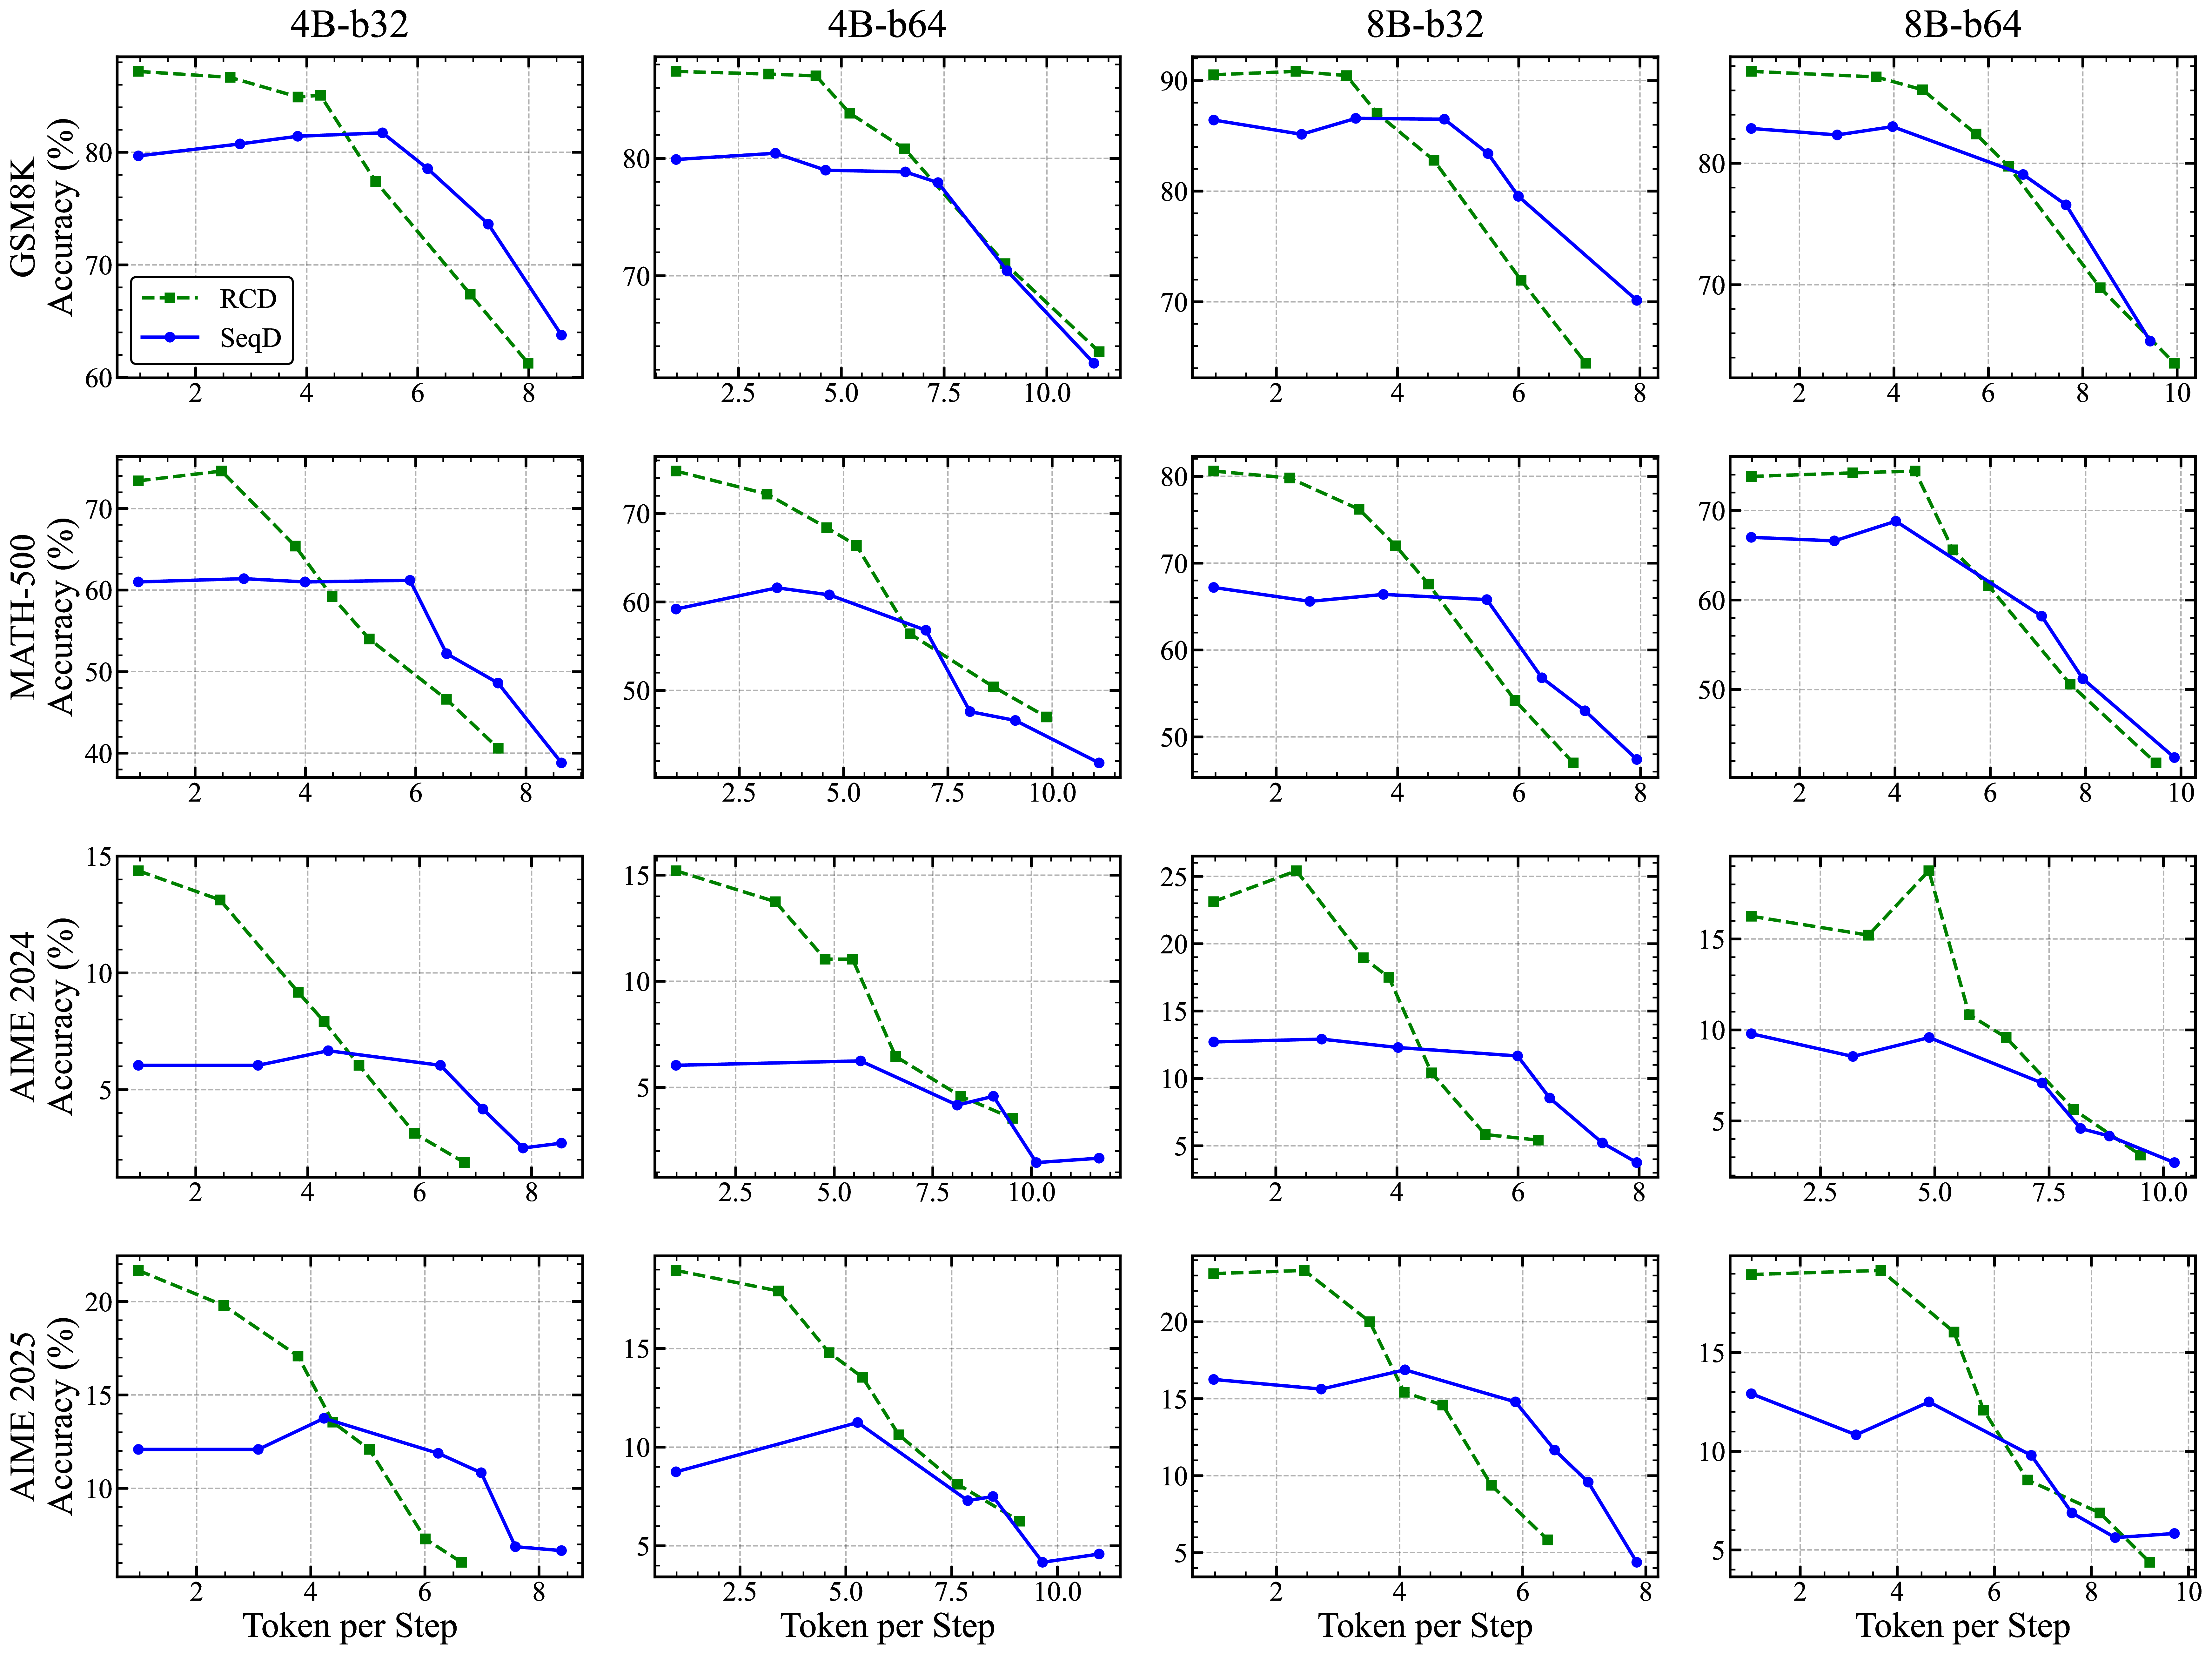
- Significant Speedup: RCD (green dashed line) consistently shifts the frontier toward the upper-left, achieving higher accuracy with fewer steps.
- Stability: RCD enables stable generation at higher Token per Step regimes where the Sequential Denoising baseline fails to maintain coherence.
- 4-5× Gain: At the baseline's peak accuracy, RCD requires up to 4–5× fewer steps on complex reasoning tasks.
Throughput in Inference Engines
In state-of-the-art inference engines, Fast-dLLM for LLaDA (8×H100, batch size 4) and D2F for SDAR (8×H100, batch size 1), RCD runs at 87–99% of the baseline's tokens per second while improving accuracy by 2–9 points:
| Benchmark | Variant | Tokens / s | Accuracy (%) |
|---|---|---|---|
| LLaDA with Fast-dLLM (block size 64, length 512) | |||
| MinervaMath | SeqD | 117.82 | 34.20 |
| RCD | 110.37 | 36.22 | |
| GSM8K | SeqD | 75.00 | 76.12 |
| RCD | 65.56 | 78.70 | |
| SDAR with D2F (block size 64, length 16,384) | |||
| MinervaMath | SeqD | 130.54 | 50.82 |
| RCD | 124.86 | 59.82 | |
| GSM8K | SeqD | 149.45 | 75.36 |
| RCD | 148.41 | 81.43 | |
Throughput-matched comparison: tokens per second and accuracy of SeqD and RCD in the same inference engine.
Ablation Studies
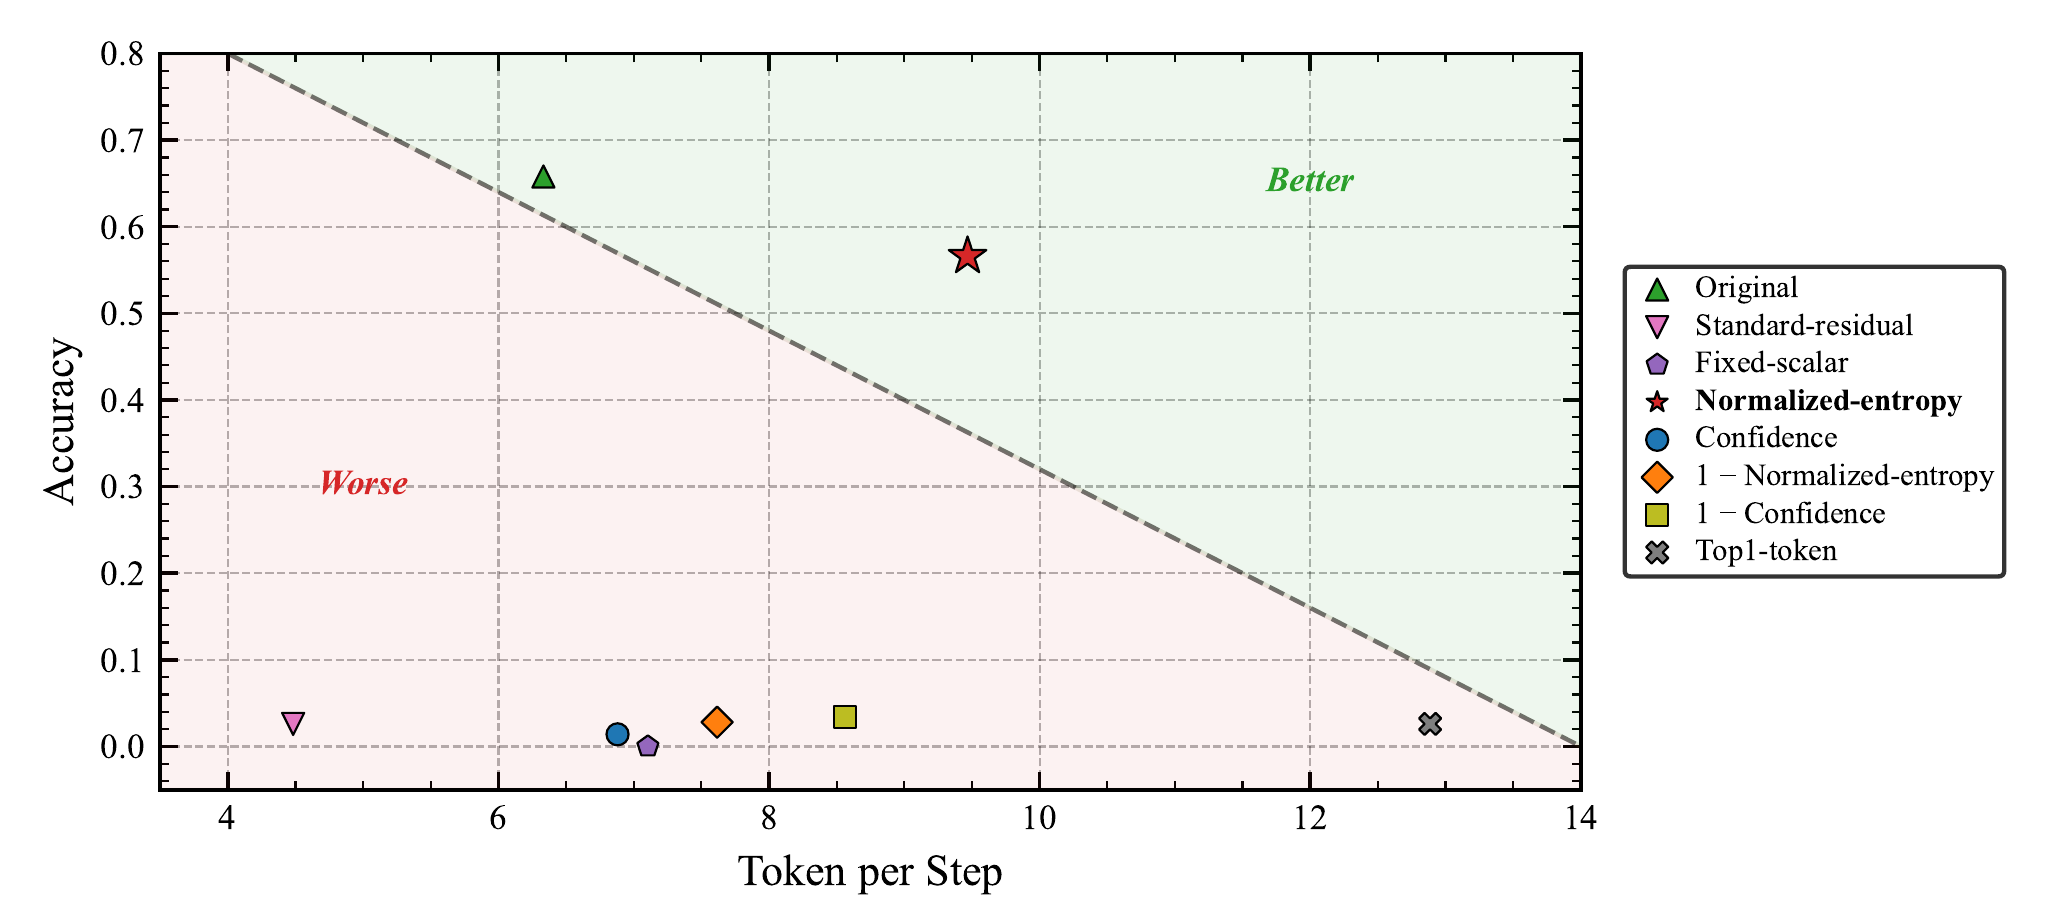
How much residual. To isolate the choice of the weight \(\alpha\) from training, an untrained SDAR-1.7B-b64 draft model guides an SDAR-8B-b64 target at every step, at a confidence threshold of 0.85. Among eight choices of \(\alpha\), the normalized entropy gives the best trade-off between accuracy and tokens per step. In this training-free setting it trails the original decoding in accuracy, a gap that fine-tuning removes; the plain residual (\(\alpha = 1\)), the top-1 token and all the other choices collapse.
Starting the residual stream. Every way of initializing the first residual without the reference model beats initializing it from a small reference model, and even a non-informative Dirichlet prior gives the best accuracy: weak signals from small reference models can mislead generation. Inference therefore does not need the reference model.
| Initialization of the residual | Reference model | MATH500 |
|---|---|---|
| SeqD baseline (no residual) | No | 64.2 |
| Reference model (1.7B) | Yes | 74.2 |
| Reference model (4B) | Yes | 71.8 |
| Extra pass of the target model | No | 76.4 |
| Zero (cold start) | No | 75.6 |
| Dirichlet prior | No | 77.4 |
MATH500 accuracy (%) of the fine-tuned SDAR-8B-b64 RCD model at a confidence threshold of 0.85, for different initializations of the residual context.
Comparison with Loopholing. Loopholing, the state-of-the-art latent method for discrete diffusion, feeds raw hidden states back into the input. Hidden states have much larger norms than input embeddings and can overwhelm the input sequence. Trained on SDAR-4B-b64 for one epoch (~300M tokens), Loopholing fails to generate valid, evaluatable outputs, while RCD reaches 86.35% on GSM8K and 66.20% on MATH500.
Not just more training. Training the SeqD baseline for 8 epochs instead of 5 improves it only modestly, and RCD, trained for 5 epochs, stays far ahead: on SDAR-8B-b64, 74.40% against 68.00% on MATH500 and 18.75% against 8.96% on AIME24. The bottleneck of standard dLLMs appears to be the information lost to remasking rather than the number of training steps.
Models and Code
All the checkpoints are on Hugging Face, with the Sequential Denoising baselines trained on the same data:
| Backbone | RCD | SeqD baseline |
|---|---|---|
| SDAR-4B, block 32 | RCD-SDAR-4B-b32-Thinking | SeqD-SDAR-4B-b32-Thinking |
| SDAR-4B, block 64 | RCD-SDAR-4B-b64-Thinking | SeqD-SDAR-4B-b64-Thinking |
| SDAR-8B, block 32 | RCD-SDAR-8B-b32-Thinking | SeqD-SDAR-8B-b32-Thinking |
| SDAR-8B, block 64 | RCD-SDAR-8B-b64-Thinking | SeqD-SDAR-8B-b64-Thinking |
| LLaDA-8B | RCD-LLaDA-8B-Instruct | SeqD-LLaDA-8B-Instruct |
The standalone generation scripts only need transformers. To generate with RCD (with seqd-sdar/ and a SeqD- model for the baseline):
git clone https://github.com/yuezhouhu/residual-context-diffusion.git
cd residual-context-diffusion
pip install transformers==4.52.3

CUDA_VISIBLE_DEVICES=0 python rcd-sdar/generate.py \
  --model_dir yuezhouhu/RCD-SDAR-4B-b64-Thinking \
  --trust_remote_code \
  --block_length 64 \
  --denoising_steps 64 \
  --temperature 0 \
  --dtype bfloat16 \
  --confidence_threshold 0.85
For batched, high-throughput inference or RL training loops, JetEngine provides a paged KV cache, fused Triton attention and MoE kernels, native block-diffusion scheduling, and the residual hidden states of RCD. The repository also contains the training recipes and the evaluation scripts for both backbones.
Citation
If you find this work useful, please cite:
@misc{hu2026residualcontextdiffusionlanguage,
      title={Residual Context Diffusion Language Models},
      author={Yuezhou Hu and Harman Singh and Monishwaran Maheswaran and Haocheng Xi and Coleman Hooper and Jintao Zhang and Aditya Tomar and Michael W. Mahoney and Sewon Min and Mehrdad Farajtabar and Kurt Keutzer and Amir Gholami and Chenfeng Xu},
      year={2026},
      eprint={2601.22954},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2601.22954},
}